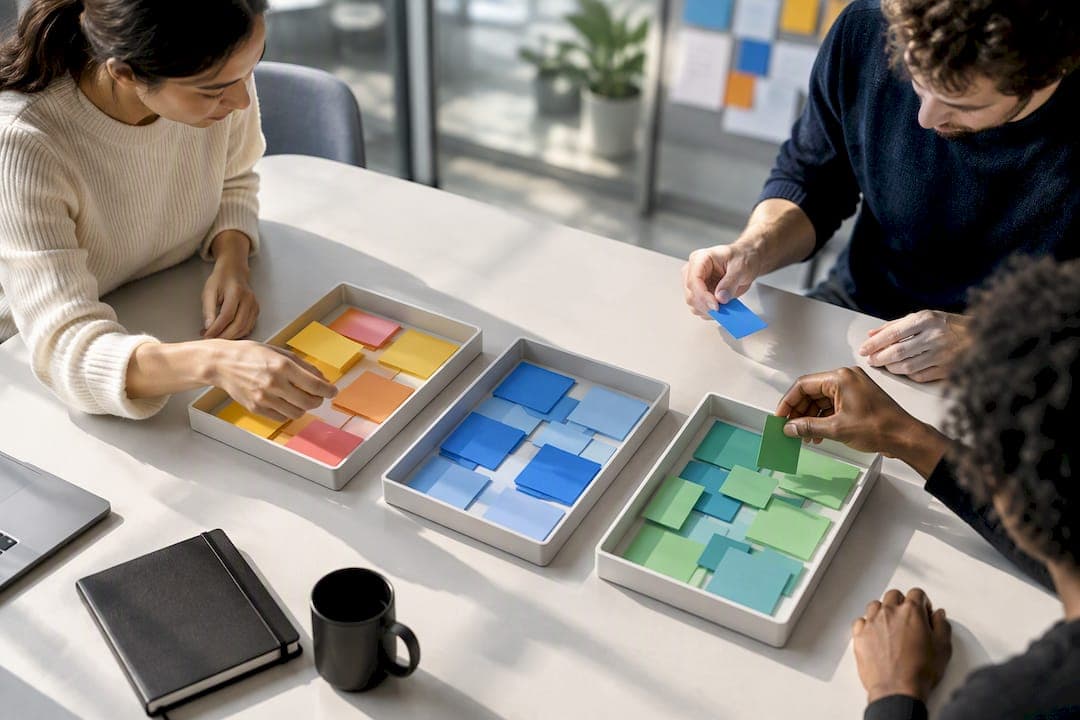
Score every backlog item with RICE, then check the top results against a simple qualitative filter, such as strategic fit or team confidence, before you commit. Pick your three highest-scoring candidates this week and run the maths on them. That single exercise will tell you more about where your roadmap should go than another quarter of debate.
TL;DR:
- Teams should primarily use RICE for prioritizing feature ideas when they have usage data and need defensible, measurable rankings.
- Combining quantitative scoring like RICE with a qualitative filter such as strategic fit is most effective for a well-aligned roadmap.
- Re-score backlog items regularly—monthly for volatile data, quarterly for stable areas—and document changes to maintain trust and relevance.
- Protect quick wins and technical debt separately in scoring to avoid overshadowing long-term strategic bets and prevent roadmap erosion.
- Use low-effort, high-reach features for fast execution but allocate a fixed capacity for high-effort, strategic initiatives to balance short- and long-term goals.
Table of Contents
- What is app roadmap prioritisation and why does it matter?
- Rice vs WSJF and other frameworks: which one fits your team?
- How do you calculate a RICE score step by step?
- Choosing a framework and setting your review cadence
- Pocket App's practitioner playbook: how we approach prioritisation
- How do you defend your roadmap to sceptical stakeholders?
- A quick scoring template you can use today
- How should user feedback and market research shape your scores?
- Balancing quick wins against your long-term roadmap
- Where does technical debt fit in the prioritisation model?
- How often should you revisit your prioritisation as new data comes in?
- When to choose speed over perfect data
- Get help running your discovery and prioritisation workshop
- Sources
- FAQ
What is app roadmap prioritisation and why does it matter?
App roadmap prioritisation is the discipline of deciding which features, fixes, and technical work get built next, and in what order, based on evidence rather than whoever argued loudest in the last planning meeting. Done well, it ties every roadmap item back to a measurable outcome, usually an OKR, so a feature earns its place because it moves a number, not because a stakeholder likes it.
Three principles separate teams that prioritise well from teams that just make lists:
- Alignment. Every item should trace back to a business objective or a specific user problem, not a hunch.
- Measurable impact. If you can't estimate what a feature will move (retention, conversion, support tickets), you can't rank it fairly.
- Realistic effort and scope discipline. Know where your product should stop solving a problem and let established tools handle the rest, rather than chasing feature parity with the entire market, a trap Intercom's product team warns against explicitly.
The trickiest part is knowing when to trust your gut and when to slow down. Product decisions split roughly into fast, pattern-matching calls and slower, analytical ones, a distinction Intercom's product thinking borrows from behavioural psychology's System 1 and System 2 model. Approving a copy tweak is a System 1 call. Deciding whether to build a payments feature or a loyalty programme next quarter deserves protected System 2 time, ideally blocked on a calendar, not squeezed between meetings.
Pro Tip: Block a recurring 90-minute slot every fortnight purely for scoring and re-scoring backlog items. Treat it like a stakeholder meeting you can't skip, because thrashing usually starts when this time gets cannibalised by "urgent" requests.
Rice vs WSJF and other frameworks: which one fits your team?
No single framework wins outright. ProductPlan's research is blunt about this: most mature teams combine a quantitative scoring method with a qualitative filter, because numbers alone don't survive contact with a sceptical stakeholder, and gut feel alone doesn't survive an audit.
Here's how the main contenders stack up:
RICE (Reach, Impact, Confidence, Effort) scores each idea numerically, giving you one comparable number per backlog item. It needs decent data (usage figures, past conversion rates) to be more than guesswork, but it's transparent and defensible when a stakeholder asks "why this, why now?"
MoSCoW (Must, Should, Could, Won't) sorts items into four buckets rather than scoring them. It's fast to run in a workshop and easy for non-technical stakeholders to grasp, but it doesn't tell you which "Must" to build first when you have six of them.
Kano classifies features by the emotional response they trigger: basic expectations, performance features, and delighters. It's genuinely useful for spotting features nobody asked for that would still thrill users, but it requires structured user surveys to do properly, which most small teams skip, and then misuse the model on assumptions instead.
Value vs effort (impact-effort mapping) plots ideas on a simple grid. It's the fastest visual method going and works well with limited data, which is why Product School flags it as a favourite for early-stage teams. Its weakness is precision: everything ends up looking like a "quick win" until you scrutinise the effort axis properly.
WSJF (Weighted Shortest Job First), borrowed from the Scaled Agile Framework, divides the cost of delay by job duration. It's built for teams juggling many concurrent workstreams and wanting a formula that favours speed of delivery. It's overkill for a five-person app team with one backlog.
When people ask about RICE vs WSJF specifically, the honest answer is that they solve different problems. RICE ranks discrete feature ideas against each other. WSJF sequences work across multiple teams or value streams where delay itself has a cost. Most app teams below enterprise scale need RICE, not WSJF.
Three rules for choosing:
- If you have usage data and need to defend decisions to sceptical stakeholders, start with RICE.
- If you need a fast workshop outcome with non-technical voices in the room, start with MoSCoW, then sanity-check the "Musts" with a lightweight RICE pass.
- If your team has abandoned a framework before because it felt like admin, pick the simplest one you'll actually maintain. ProductPlan's own guidance is clear that framework fatigue kills more roadmaps than a "wrong" framework choice ever does.
How do you calculate a RICE score step by step?
RICE breaks into four inputs, each easier to estimate with a fixed scale than an open guess.
- Reach: how many users will this touch in a given period? Use a scale tied to real numbers, such as monthly active users. If you have a substantial user base and a feature affects checkout, your reach is roughly the number of monthly users who check out.
- Impact: how much will it move the needle for each user who's reached? Use a multiple-choice scale: 3 for massive impact, 2 for high, 1 for medium, 0.5 for low, 0.25 for minimal. Avoid guessing decimals beyond that; false precision just slows the meeting down, a point the MoSCoW glossary makes about scoring generally.
- Confidence: how sure are you about reach and impact? Score 100% for hard data, 80% for solid assumptions, 50% for guesses.
- Effort: estimate in person months. Round to the nearest half month.
The formula: (Reach × Impact × Confidence) ÷ Effort = RICE score.
Take three hypothetical features:
- Guest checkout: Reach 8,000, Impact 2, Confidence 80%, Effort 2 months. Score: (8,000 × 2 × 0.8) ÷ 2 = 6,400.
- In-app referral programme: Reach 3,000, Impact 3, Confidence 50%, Effort 3 months. Score: (3,000 × 3 × 0.5) ÷ 3 = 1,500.
- Dark mode: Reach 12,000, Impact 0.5, Confidence 100%, Effort 1 month. Score: (12,000 × 0.5 × 1) ÷ 1 = 6,000.
Guest checkout edges dark mode, and both dwarf the referral programme, largely because confidence is dragging that score down. That's the correct read: treat low confidence as a warning, not just a discount. Rather than building blind, run a small proof of concept or a lightweight prototype to raise your confidence score before committing engineering months to it. Once you've ranked scores, check dependencies before locking sequencing. Guest checkout might score highest but still need the payments API that dark mode doesn't touch, which can flip your build order regardless of the numbers.
Choosing a framework and setting your review cadence
Before adopting any method, run through a short checklist: do you have OKRs the roadmap should serve, do you have usage data to feed a quantitative score, does your team have the capacity to maintain scoring discipline, and do stakeholders expect visible rigour or just a clear story?
Cadence matters as much as the framework itself. Atlassian's guidance on agile roadmaps recommends structuring reviews around multiple time horizons rather than one big annual reset.
- Weekly triage: quick bug fixes and support-driven requests, no full RICE pass needed.
- Monthly scoring: re-score the near-term backlog as new usage data lands.
- Quarterly roadmap review: check strategic alignment against OKRs and reshuffle "later" items into "next".
The rule that stops teams thrashing: tie your re-scoring frequency to how fast your signal changes, not to how often someone feels anxious about the backlog. A newly launched feature with volatile usage data deserves monthly attention. A mature, stable product area can survive a quarterly look.
Pro Tip: Keep your roadmap horizons loose, "now, next, later" rather than fixed dates. Committing to exact ship dates two quarters out invites the exact thrashing your cadence rules are trying to prevent.
Pocket App's practitioner playbook: how we approach prioritisation
Across more than 300 projects, the pattern that works looks the same regardless of sector: discovery first, scoring second, a short prototype cycle third, then measure and repeat. Skipping straight to scoring without proper discovery produces confident-looking numbers built on weak assumptions, which is worse than admitting you don't know yet.
Common pitfalls we see teams fall into, and the fix for each:
- Over-scoping the roadmap. Trying to plan twelve months of exact features. Fix: commit hard only to the next quarter, keep the rest directional.
- Treating low confidence as acceptable. Building on a 50% confidence score without validating first. Fix: run a fast prototype or user research pass before committing budget.
- Ignoring dependencies until sprint planning. Discovering the payments integration blocks three "quick wins" only after work starts. Fix: map dependencies during scoring, not after.
- Chasing feature parity instead of scope discipline. Fix: define where your app's job starts and stops, and resist building what a market leader already does well.
If your team is earlier than that, an MVP approach forces the same discipline before you've built anything to prioritise at all.
How do you defend your roadmap to sceptical stakeholders?
Numbers alone rarely win a roadmap argument. A stakeholder who disagrees with your sequencing wants to understand the reasoning, not just see a score, which is why Intercom's guidance on fast and slow product thinking stresses surfacing the "why" behind trade-offs, not just the "what".
The most durable approach pairs two things: the score and the story. Show your RICE numbers openly, including the inputs, not just the final figure. When a marketing lead questions why guest checkout beat the referral programme, walking through reach, impact, and confidence individually turns a debate about opinion into a conversation about assumptions. If they think your confidence estimate on the referral programme is too low, that's a productive disagreement. You can go and test it.
Narrative matters just as much as transparency. Frame each roadmap decision around the business outcome it serves, not the feature itself. "We're building guest checkout because it unblocks an estimated 8,000 monthly sessions currently abandoning at the payment step" lands harder than "guest checkout scored 6,400."
Keep a simple one-page rationale alongside your roadmap tool, listing the top five items, their scores, and a single sentence on the business reason each one made the cut. When priorities shift, and they will, that document lets you show what changed (new data, a lower confidence score, a dependency surfaced late) rather than looking like you're reacting to the most recent loud opinion in the room.
Expect pushback on effort estimates more than anything else. Engineering leads will often argue a score is wrong because effort was underestimated. Treat that as useful signal, re-score with their input, and move on. Defending a roadmap isn't about winning the argument. It's about showing your working clearly enough that disagreement becomes a discovery task rather than a stalemate.

A quick scoring template you can use today
You don't need software to start. A shared spreadsheet with six columns does the job for most teams under twenty people.
Set up columns for: Feature name, Reach, Impact, Confidence, Effort, and RICE score (a simple formula: Reach × Impact × Confidence ÷ Effort). Add a seventh column for Dependencies and an eighth for Notes on confidence, capturing why you scored confidence the way you did, so future-you remembers whether it was based on data or a guess.

Populate it with your current top ten backlog items in one sitting. Don't aim for perfect numbers on the first pass. The goal is relative ranking, not absolute truth. If two items land within a few hundred points of each other, treat them as roughly equal and let other factors, dependencies, strategic timing, team enthusiasm, break the tie.
A minimal version, scoring three items at once, might look like this:
| Feature | Reach | Impact | Confidence | Effort (months) | RICE score |
|---|---|---|---|---|---|
| Guest checkout | 8,000 | 2 | 80% | 2 | 6,400 |
| Dark mode | 12,000 | 0.5 | 100% | 1 | 6,000 |
| Referral programme | 3,000 | 3 | 50% | 3 | 1,500 |
Re-run this exercise monthly rather than treating it as a one-off exercise you did during planning week. Backlog items decay in relevance fast: a feature that scored well three months ago might have been overtaken by a new competitor move, a support ticket spike, or simply better data replacing an old guess. The template only stays useful if it's a living document, not a artefact from a single meeting.
How should user feedback and market research shape your scores?
Your RICE inputs are only as good as the evidence behind them, and the biggest single upgrade most teams can make is tightening the link between user feedback and the Reach and Impact numbers specifically.
Impact scoring improves when it's grounded in something a user actually said or did, rather than a stakeholder's assumption about what users want. A feature request that surfaces unprompted in customer interviews deserves a higher confidence score than one nobody has mentioned but a product manager suspects would help.
Market research plays a different role: it's less about scoring individual features and more about spotting entire categories you're missing. If competitor apps in your space have normalised a particular flow (biometric login, one-tap reorder), that shifts your Impact estimates upward for matching features, not because copying competitors is inherently smart, but because it resets user expectations for the whole category.
The trap to avoid is treating feedback as a mandate rather than an input. Ten vocal users asking for a niche feature doesn't automatically outrank a quieter but broader pain point buried in analytics. Weight qualitative feedback against quantitative usage data before it moves a RICE score, and be explicit in your notes about which evidence type drove which number. That transparency is what lets you defend a score later when someone asks "but three customers said they wanted X."
Balancing quick wins against your long-term roadmap
Every roadmap has a tension between features that prove momentum this quarter and infrastructure that pays off eighteen months from now, and RICE scoring alone won't resolve it, because a high-effort strategic bet will often score lower than a small UX fix purely on the maths.
The fix isn't to abandon scoring. It's to score within separate buckets. Run RICE against your quick-win candidates (low effort, month or two, moderate reach) separately from your strategic bets (high effort, quarter-plus, tied directly to a company-level OKR). Comparing a two-week UX tweak against a three-month platform rebuild on the same scale distorts both.
Protect that allocation the way you'd protect any budget line. Otherwise, quick wins will quietly eat the entire roadmap, because they're always easier to justify in a Monday planning meeting than a bet that won't show results for two quarters.
Low-effort, high-reach UX improvements are worth a dedicated lane of their own precisely because they're so easy to underrate against splashier features. A step-by-step UX improvement pass often clears several quick wins in the time a single strategic feature takes to spec properly, which is exactly why they deserve separate scoring lanes rather than direct competition.
Where does technical debt fit in the prioritisation model?
Technical debt loses almost every head-to-head RICE comparison against a customer-facing feature, because its Reach and Impact numbers are genuinely hard to estimate against a metric like conversion or retention. That's precisely why it needs its own allocation rather than a seat at the same table.
Treat technical debt and maintenance the way you'd treat the strategic bets bucket above: ring-fence a fixed slice of capacity, commonly somewhere between 15% and 25% of a sprint or quarter depending on how much legacy code your app carries, and protect it from being reallocated every time a stakeholder pitches an urgent feature.
Within that ring-fenced slice, you can still prioritise. Not all technical debt is equal. Score debt items on a simplified two-factor version of RICE: risk (what breaks, and how badly, if this isn't fixed) against effort. A fragile authentication flow that's one edge case away from locking out real users outranks an outdated internal admin tool nobody but your own team touches.
The mistake to avoid is waiting until debt causes a visible incident before it gets roadmap attention. By then, you're not prioritising, you're firefighting, and firefighting always costs more engineering time than the equivalent scheduled fix would have. Build technical debt review into your monthly scoring cadence, not just your incident retrospectives, so it competes for attention on a schedule rather than only during a crisis.
How often should you revisit your prioritisation as new data comes in?
Prioritisation isn't a document you finish. It's a loop you run, and the biggest single failure mode isn't picking the wrong framework, it's picking a good one and then never updating the inputs once the initial scoring session ends.
Tie your revisit frequency to how fast the underlying signal actually moves, echoing the same principle behind Atlassian's cadence guidance on multiple review horizons. A newly launched feature generating fresh usage data weekly deserves a monthly re-score at minimum. A stable, mature product area with slow-moving metrics can survive a quarterly look without anything meaningful changing in between.
Build in specific triggers that force an off-cycle re-score regardless of calendar timing: a confidence score based on assumption that's now backed by real data, a dependency that surfaced late and changes effort estimates, a competitor shipping something that resets Impact expectations for a whole category, or a support ticket spike that suggests Reach was undercounted. Any one of those is a legitimate reason to reopen the spreadsheet outside your normal monthly slot.
Keep a lightweight changelog next to your scoring template, noting what changed and why, each time you re-score. Six months from now, when someone asks why a feature that scored highly in January slipped to third place by June, that changelog is the difference between "the data changed and here's how" and "priorities just moved," which is exactly the kind of answer that erodes stakeholder trust in the whole exercise.
When to choose speed over perfect data
Waiting for complete data before scoring anything is its own kind of failure. My rule of thumb: if a decision is reversible and the cost of being wrong is a sprint, score it fast with System 1 judgement and move on. If it's a quarter-defining bet with real switching costs, protect proper System 2 time and don't let a stand-up rush it.
The teams that get this wrong usually err in one direction consistently, either analysing every minor decision to death or gut-calling every major one. Match your rigour to the size of the bet, not to how confident you feel that morning.
— Paul
Get help running your discovery and prioritisation workshop
Reading about RICE scoring is one thing. Running a structured session with engineering, design, and stakeholders in the room, and coming out the other side with a defensible roadmap, is another. That's where a facilitated discovery process earns its keep: an outside team can ask the awkward scoping questions your own team is too close to raise, and turn a vague backlog into scored, sequenced work within days rather than weeks of internal debate.
We offer discovery and design workshops built around the scoring and dependency-mapping approach covered here, drawing on extensive experience in delivering projects for a variety of brands. If your roadmap needs an outside eye before your next planning cycle, or you're stuck on a handful of features you can't rank with confidence, a Mobile App Clinic is a low-commitment way to get a second opinion on your top candidates before you commit a quarter of engineering time to the wrong one. Get in touch to book a session.
Sources
- Agile roadmaps: Build, share, use, and evolve | Atlassian
- Product management frameworks | ProductPlan
FAQ
How do you prioritise a product roadmap?
Score your backlog with a quantitative method like RICE to rank items by reach, impact, confidence, and effort, then apply a qualitative filter, such as strategic fit or OKR alignment, to catch anything the numbers miss. ProductPlan's research confirms that combining both approaches beats relying on either alone.
What's the best app for creating a project roadmap?
There's no single best tool; the right choice depends on whether your team needs simple visual boards, deep integration with engineering tickets, or robust OKR tracking. Whatever tool you choose, the framework behind your scoring matters more than the software displaying it.
Can ChatGPT create a roadmap?
ChatGPT can help draft roadmap structure, summarise research, or suggest RICE scoring inputs based on data you provide, but it can't reliably estimate real reach, impact, or effort figures for your specific product without your actual usage data. Treat it as a drafting assistant for the narrative, not a substitute for scoring your own backlog.
What is the best prioritisation framework?
There isn't one best framework for every team; ProductPlan's guidance is explicit that the strongest approach usually combines a quantitative method like RICE with a qualitative check for strategic fit. The framework that works is the one your team will actually keep using past the first planning cycle.
How is RICE different from WSJF?
RICE ranks individual feature ideas against each other using reach, impact, confidence, and effort, making it well suited to a single app team's backlog. WSJF divides cost of delay by job size and was built for sequencing work across multiple teams or value streams, which makes it more relevant to larger, multi-squad organisations than to a typical app roadmap.